What robots.txt does
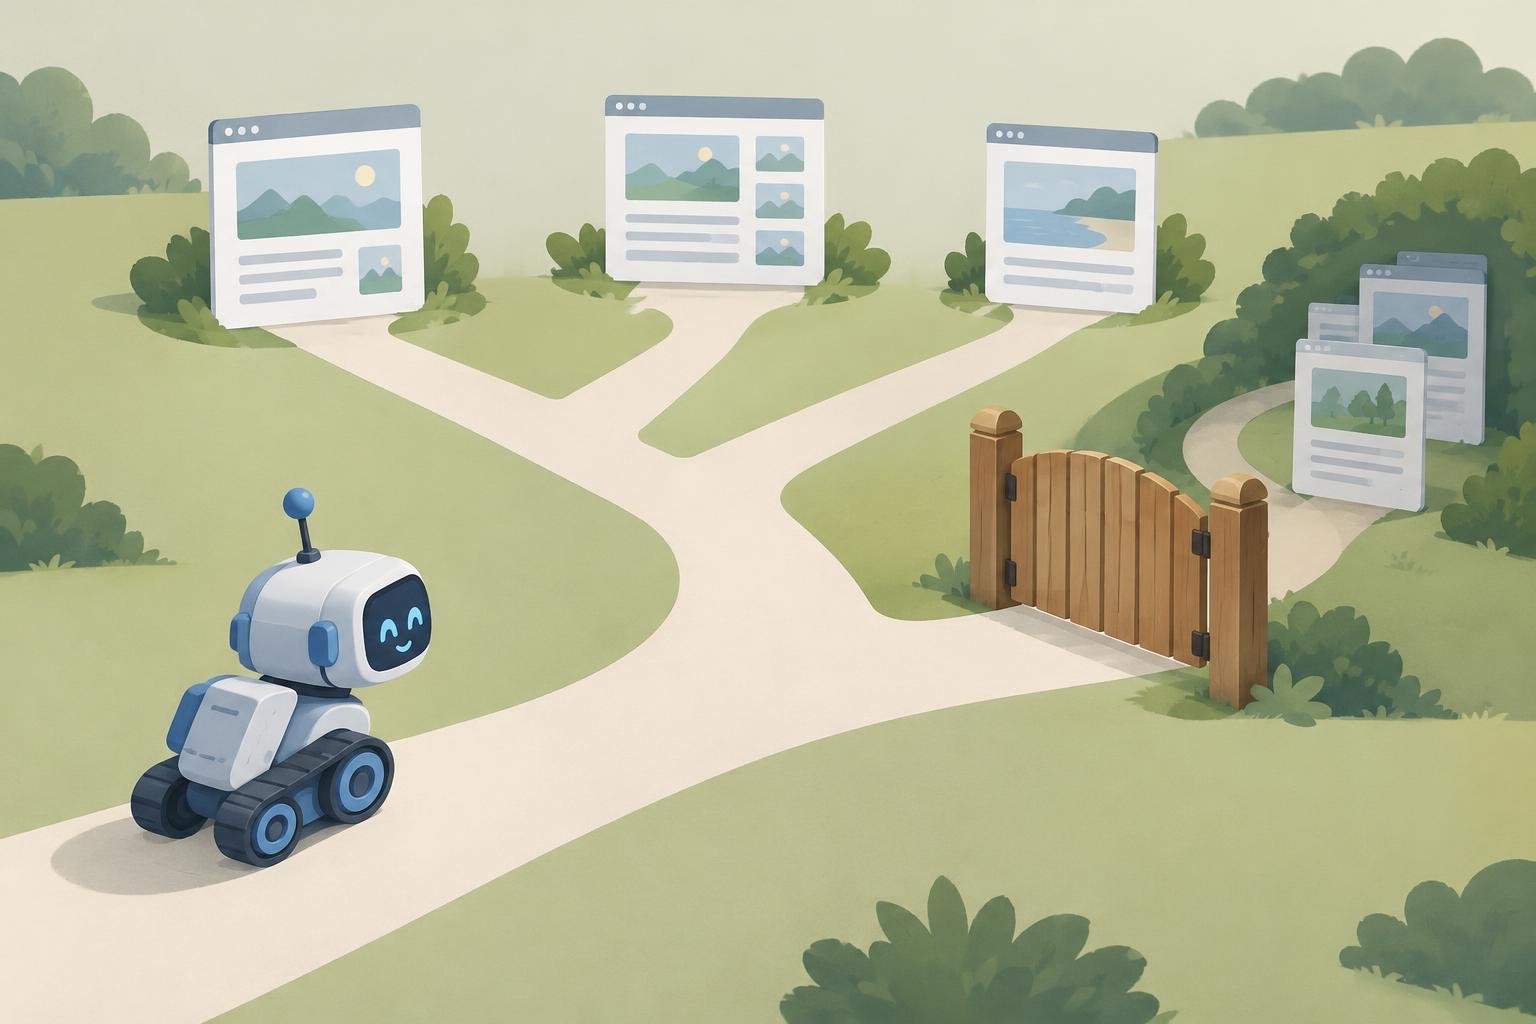
A robots.txt file gives crawlers instructions about which paths on a website they may fetch. It is a crawl-management tool, not a switch that makes content private. Search engines generally check the file before crawling a site, but compliance depends on the crawler. A person using a browser can still request a disallowed URL, and a crawler that ignores robots.txt can request it too.
The file belongs at the root of a host, such as https://example.com/robots.txt. Rules for one host do not automatically govern another, so a subdomain needs its own file. Rules can also differ between HTTP and HTTPS versions. This matters when a site has a shop, help center, or staging area on a separate host. Before writing rules, list the hosts and URL paths you actually want to manage.
How a basic rule works
A robots.txt file groups rules by user-agent, the name a crawler uses to identify itself. A rule beginning with “User-agent: *” addresses crawlers that follow the general group. “Disallow: /drafts/” asks them not to fetch URLs under that path. “Disallow: /” asks them not to crawl the whole host, while an empty Disallow value places no restriction in that group. Some crawlers also support Allow rules for exceptions, but interpretations and supported pattern features can vary. Keep rules simple unless you have a clear reason to add complexity.
Paths are easy to mistake. Blocking /drafts/ does not necessarily block a differently named path such as /draft/, and a rule aimed at one folder may cover more URLs than intended if the site uses that prefix elsewhere. Check the actual URLs generated by your site rather than relying on menu labels. A Sitemap line can point crawlers to a sitemap, but it does not override a Disallow rule or guarantee that any listed page will appear in search results.
What robots.txt cannot do
Disallowing a URL does not guarantee that it will disappear from search results. A search engine may learn that the URL exists through links or other references and display the URL without crawling its contents. Robots.txt also does not delete a page, prevent direct visits, or protect confidential information. If a file should not be public, use appropriate access controls or remove it from the public site; do not depend on a crawler instruction for security.
Robots.txt is also the wrong place to rely on a noindex instruction. If you want a public page to be crawlable but excluded from search results, a supported noindex directive on the page or in its HTTP response is generally the more suitable signal. The crawler must be allowed to fetch the URL to see that signal, so blocking the same URL in robots.txt can work against that goal. If a page is gone, return an appropriate unavailable response, such as 404 or 410, rather than using Disallow as a substitute. Search results may take time to reflect a change.
When blocking crawl can be useful
Crawl restrictions can help keep cooperative crawlers out of URL patterns that offer little value to search users, such as certain internal search results or repetitive parameter combinations. First consider whether those URLs need to exist and whether links, navigation, or URL design could be improved. Robots.txt is most useful when the problem is unwanted fetching, not simply a wish to change which page ranks.
Be careful with resources a crawler may need to understand a page. Blocking stylesheets, scripts, or images can make it harder for a search engine to render or evaluate the page as visitors see it. Likewise, a broad rule added to suppress one troublesome folder can accidentally block product pages, articles, or other useful content. Treat every Disallow rule as a change to what crawlers can inspect, not as harmless housekeeping.
A safe workflow for changes
Start with a specific purpose: identify the URL pattern, why crawling it is undesirable, and which crawlers the rule should address. Draft the narrowest rule that fits. Test representative URLs that should be blocked and URLs that must remain accessible, including close matches and important pages deeper in the site. Where available, use the relevant search engine’s robots testing or URL inspection tools to check how it interprets the rule.
After publishing, fetch the robots.txt file directly to confirm the intended version is available on the right host. Check important pages and resources again, then monitor crawl and indexing reports for unexpected effects. If you later change how URLs are generated, revisit the rules: a path that was safe to block before may contain valuable pages after a redesign. Robots.txt works best as a small, documented part of site maintenance, alongside sensible site structure and clear page-level indexing signals.