What a server log can tell you
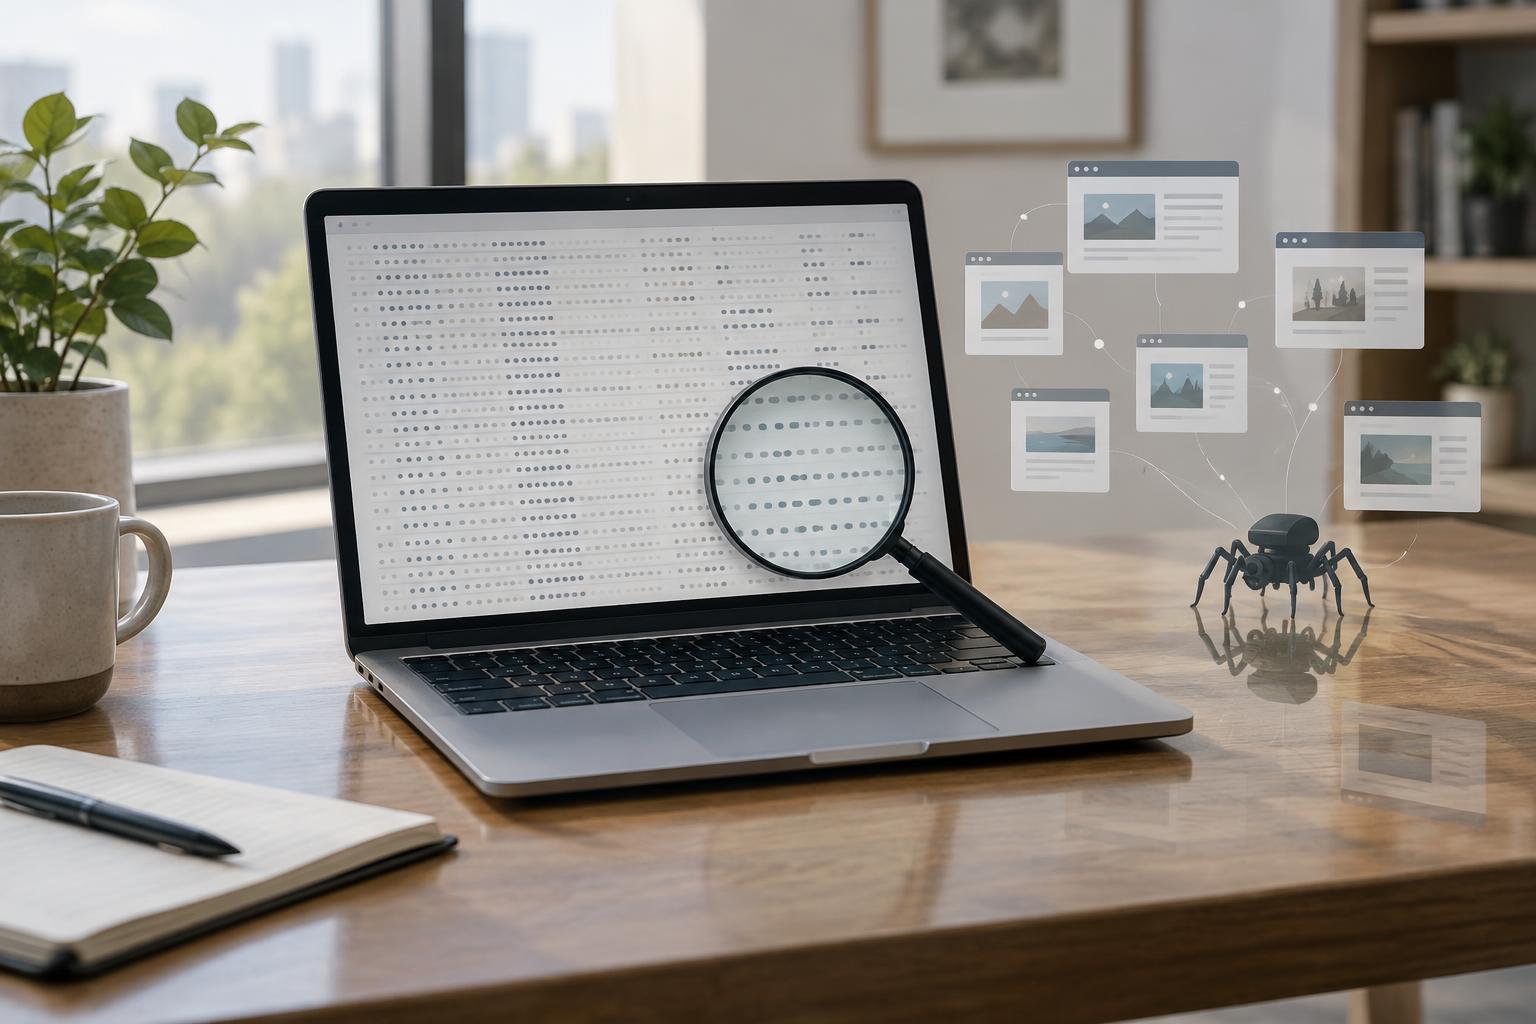
A server access log records requests handled by a web server. Depending on its format, an entry may include the request time, requested URL, HTTP method, response status, user-agent, client IP address, and response size. For technical SEO, these details help answer a specific question: which URLs did a search bot request, and what response did it receive?
Logs show observed requests, not everything a search engine knows about your site. A requested page is not necessarily indexed, and a page absent from a log sample is not necessarily undiscovered. Your view may also be incomplete if a content delivery network, cache, or another server layer handles requests without writing them to the log you are reading. Treat logs as one source of evidence alongside your sitemap, crawl data, and search engine tools.
Start with the right files and fields
Ask your hosting or infrastructure team where access logs are stored and what each file covers. Confirm whether the files include requests served through a content delivery network, and whether log rotation or retention limits the period available. If your site uses more than one hostname or server, gather the relevant files before drawing conclusions about the whole site.
Check the log format before filtering. You need a reliable way to distinguish the requested path from its query string, the response status from other numbers, and the client IP from any proxy-related address. Note the time zone so requests can be compared across files. Work from a copy rather than editing the original logs, and restrict access to raw files: IP addresses and other request details can be sensitive. For a first review, a short, representative period is easier to handle than every log you retain.
Identify bot requests carefully
Filtering for a familiar bot name in the user-agent field is a useful starting point, but it does not prove who made the request. User-agent strings can be copied. If verification matters, follow the search provider’s published bot-verification method, which may involve checking an IP address against its documented ranges or confirming reverse and forward DNS results. Avoid treating an unverified user-agent match as a confirmed search bot.
Once you have a defensible set of requests, group them by URL and response status. Keep the query string available for inspection even if you also group requests by path: different parameters can generate distinct crawlable URLs. Separate HTML pages from images, scripts, stylesheets, and other files when your question concerns page crawling. Look at request times as well as totals; repeated requests to a URL can reflect routine recrawling rather than a problem.
Look for patterns worth investigating
Start with important pages. Are bots requesting your main category pages, useful articles, and other URLs you expect them to reach? If an important URL is missing, check whether it appears in internal links and your sitemap, then inspect any relevant crawl restrictions. A missing request in the period you examined is a prompt to investigate, not proof that the URL is inaccessible.
Next, review the responses bots receive. Repeated 404 responses may reveal broken internal links or outdated URLs that still attract requests. Redirects may be appropriate, but long redirect chains create unnecessary steps. Server errors deserve attention, especially when they affect important URLs. Also examine requests to parameter combinations, internal search results, or near-duplicate paths. A large collection of such URLs can suggest that navigation or URL rules need closer inspection. Check the underlying pages before changing rules: a frequently requested URL may have a valid purpose.
Turn observations into a repeatable check
Write down each finding as a testable question. For example: Which internal link leads to this 404? Does a redirect point directly to its intended destination? Are bots finding parameter URLs through links that could use a simpler format? Then make a targeted change, confirm it works for visitors, and review later logs to see what requests your server actually receives. This approach is more useful than trying to increase or decrease a raw bot-request count.
Keep a simple record of the log period, files examined, bot-verification method, filters, and URL groups used in each review. That context makes comparisons more meaningful when your site or logging setup changes. Server logs are most valuable as a diagnostic tool: they show how your server responded to observed requests and help you decide where to investigate next. They do not, by themselves, explain rankings or guarantee that a technical change will alter search visibility.