Know what you are looking for
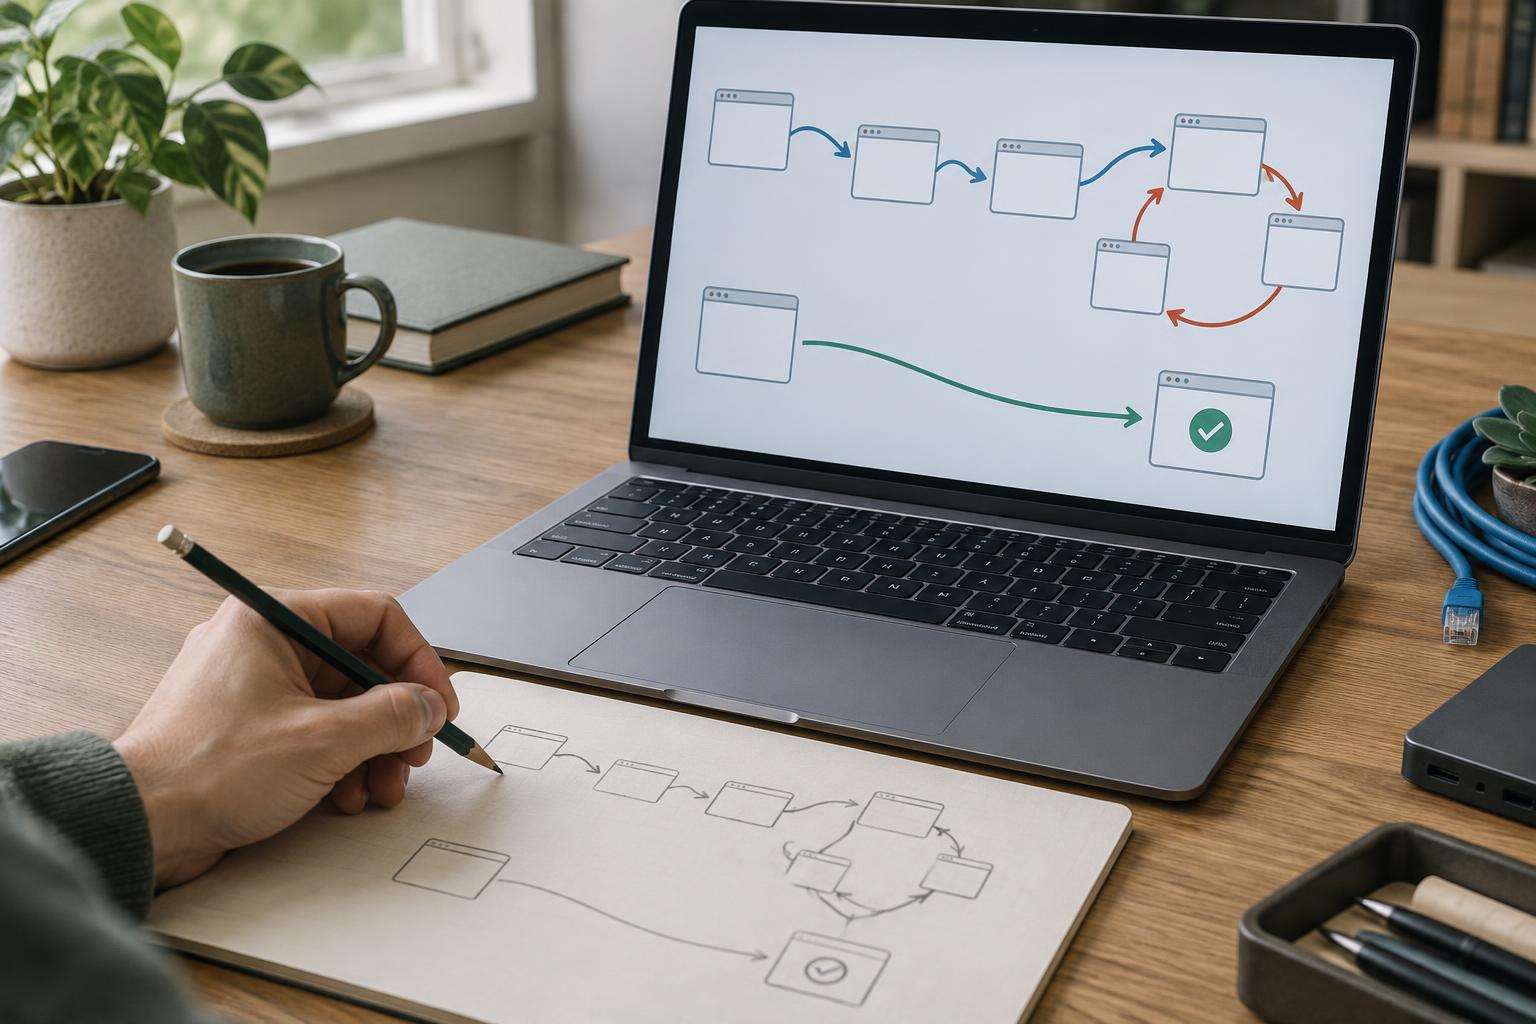
A redirect tells a browser or crawler to request a different URL. This is useful when a page moves or when you choose one preferred version of a site, such as an HTTPS address. A redirect chain occurs when the first URL sends the visitor to a second URL, which then sends them to a third. A loop occurs when redirects eventually point back to a URL already visited, so the final page never loads.
One redirect is often expected. For example, an old page may send visitors straight to its replacement. The diagnostic question is whether each additional hop is necessary and whether the path ends at the intended, accessible page. A chain may add requests and make a site harder to maintain; a loop is more urgent because it blocks access.
Trace the full path, not just the first hop
Start with one affected URL and write down its exact form, including the protocol, hostname, path, trailing slash, and any query string. Test that URL with a redirect-checking tool or an HTTP client that can show individual responses. Record each response status and the destination in its Location header until you reach a page that does not redirect. A browser can confirm what a visitor experiences, but it may hide intermediate steps or reuse cached redirects.
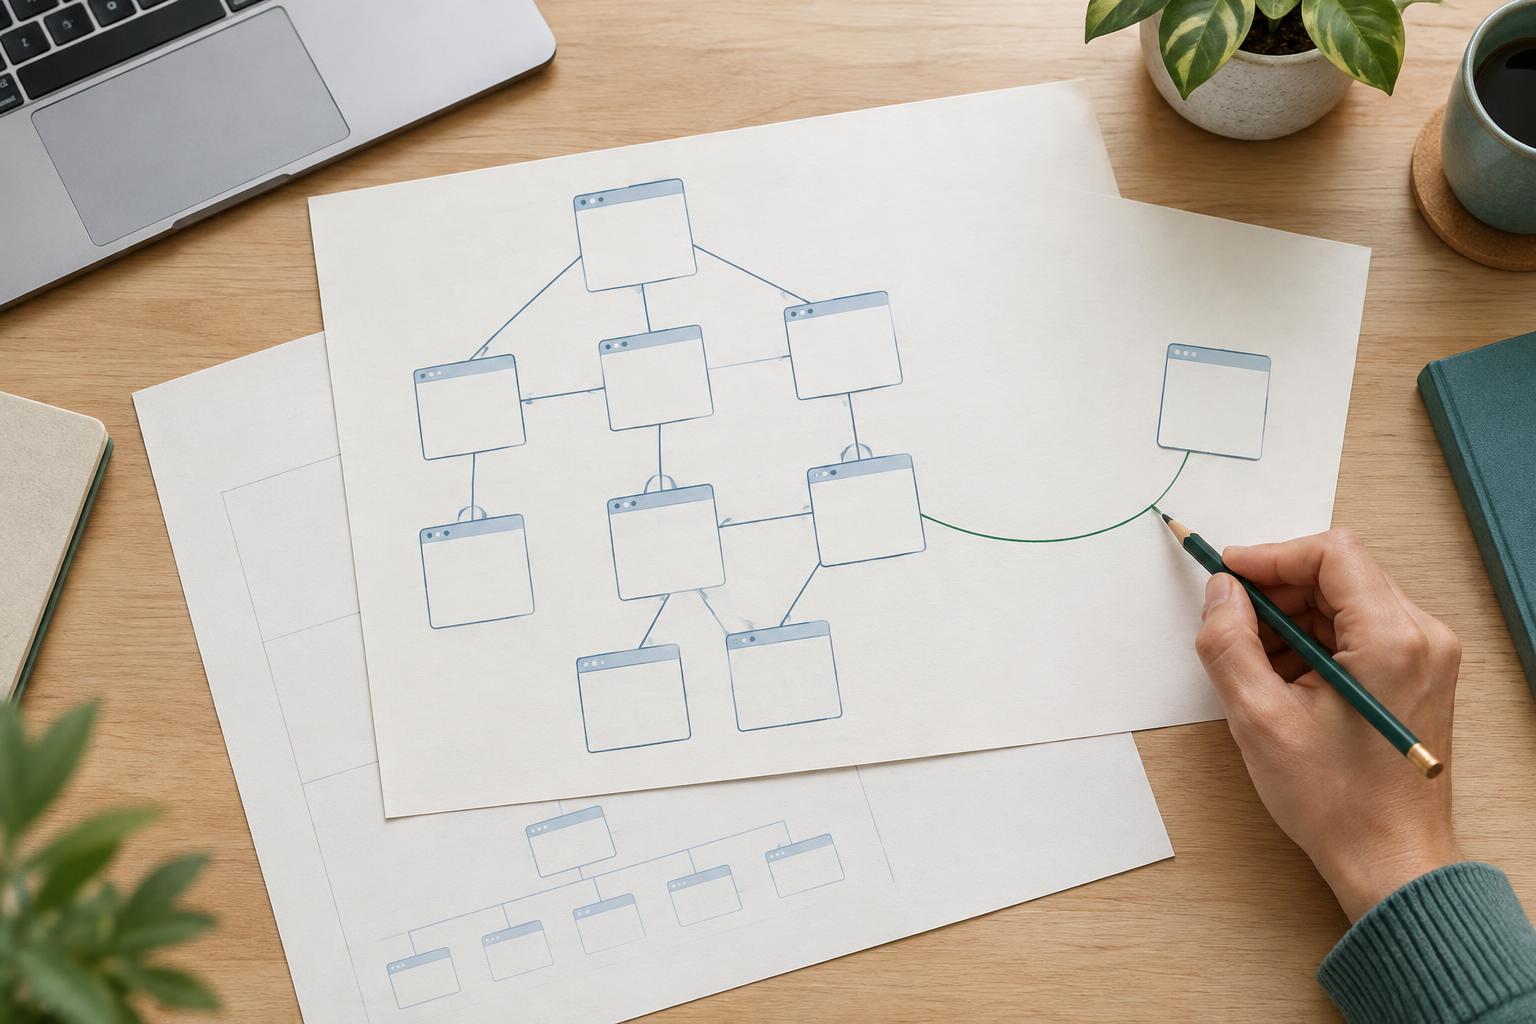
Compare several entry points: the old URL, the expected destination, the HTTP and HTTPS versions, and any relevant www and non-www versions. If the issue affects only certain pages, test both an affected page and a working one. Where practical, check whether a query string changes the result. Keep a short record such as “old path → site homepage → new path → final page.” That makes the unexpected hop easier to spot. If the path repeats a URL or the client reports too many redirects, you have likely found a loop.
Find the rule responsible for a chain
Work backward from the first unnecessary hop. Common causes include an old redirect that points to another retired URL, a sitewide HTTP-to-HTTPS rule combined with a separate hostname rule, or a page-level rule that runs after a broader rule. A content management system, server configuration, hosting control panel, or edge service may each set redirects. Check every layer that could handle the request rather than assuming the visible page settings control the whole path.
For a page that has moved more than once, update the old URL’s redirect to point directly to the current destination when you can. Keep redirects for old URLs that people may still use, but avoid making those URLs depend on intermediate pages that might move again. If several sitewide rules are involved, choose a clear preferred protocol and hostname, then test how every common variant reaches it. The goal is a predictable route, not simply the fewest rules in a settings screen.
Break loops by checking for conflicting conditions
A loop often comes from two rules that disagree. One layer might redirect a URL with a trailing slash to a version without one, while another does the reverse. Or a server may redirect to HTTPS while a service in front of it treats the request as HTTP and sends it through the same rule again. A page-level redirect can also point back to an earlier URL after a sitewide rule has changed it.
Look for the first URL that appears twice in your trace. Then inspect the rules that produced the responses on either side of that repeat. Check their matching conditions, order, and destinations, including whether they apply to the destination itself. Change one rule at a time where possible, and retest the original entry URL after each change. Avoid a quick fix that merely shifts the loop to another URL variant or page.
Verify the destination and keep a record
After changing redirects, trace the same entry points again. Confirm that each arrives at the intended page, that the final page loads successfully, and that it does not immediately redirect elsewhere. Test a few related URLs to catch rules that match more broadly than expected. If a permanent move is intended, check that the redirect type matches that intent; temporary changes may call for a different response. Also check internal links and navigation, updating them to point directly to the preferred URLs rather than relying on redirects.
Save the before-and-after paths and note which rule changed. This gives you a reference if a later site update introduces another hop. Redirect diagnosis is easier when you treat each URL as a traceable route: follow every response, identify the rule that changes the route unexpectedly, and confirm that the corrected route reaches the right page.