The journey from page to search result
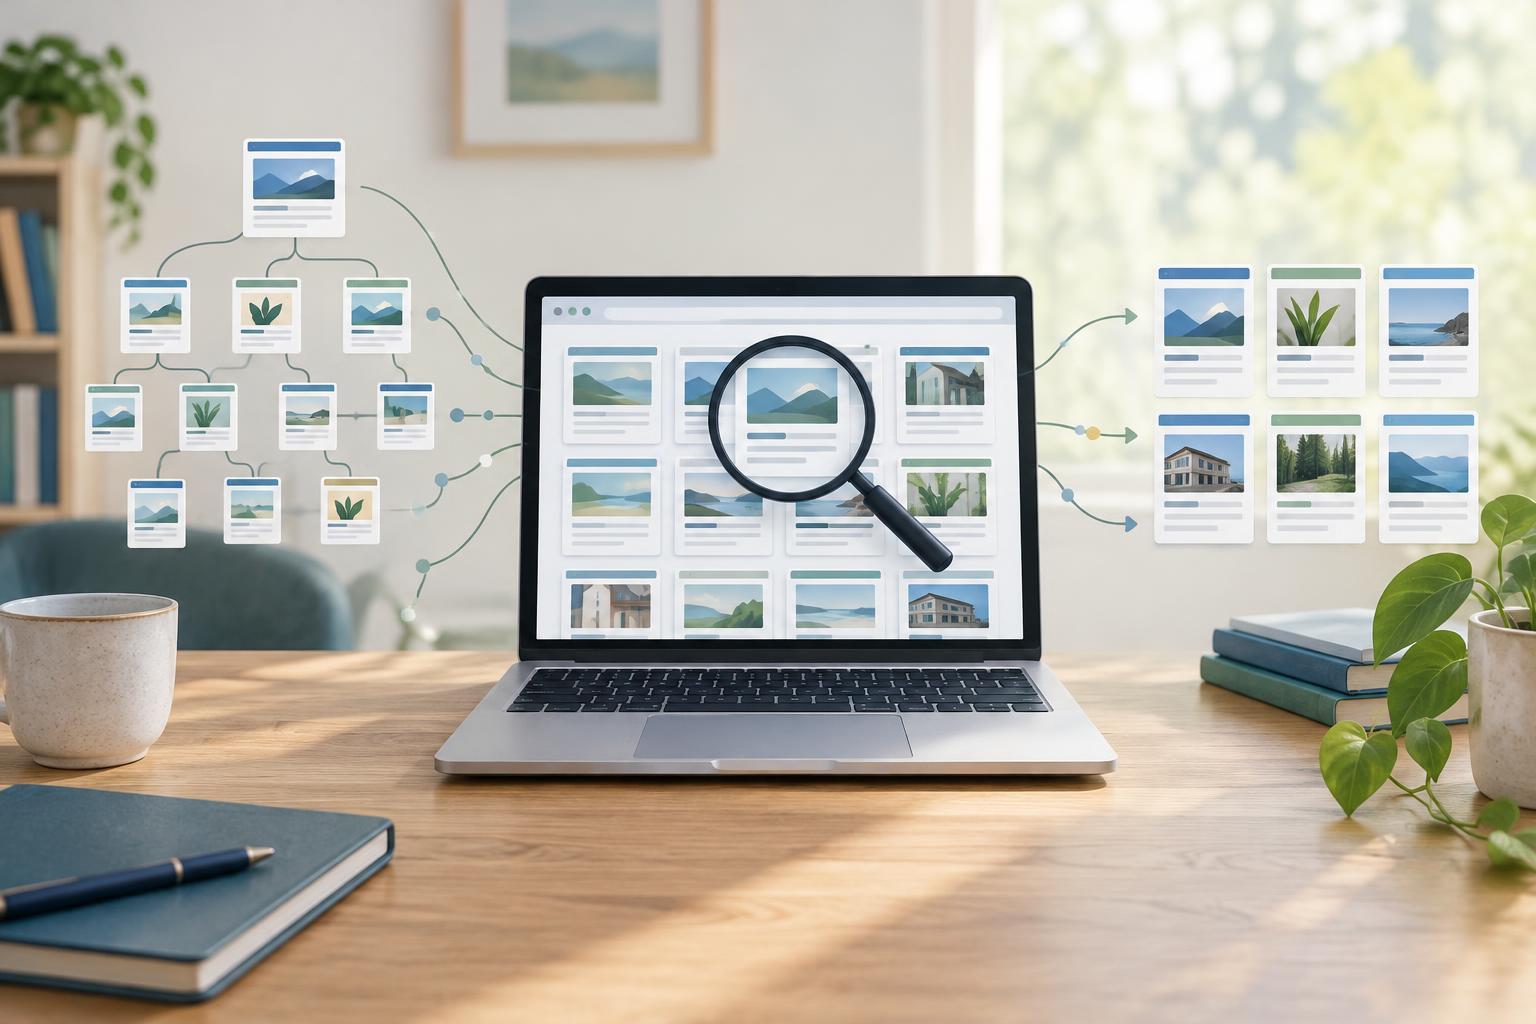
Publishing a page does not automatically put it in search results. Search engines first need to discover its address, access and interpret its contents, decide whether to include it in an index, and determine when it is relevant to a search. These stages are often called discovery, crawling, indexing, and ranking.
The distinction matters when you troubleshoot a page. If a search engine has not found it, rewriting the headline may not solve the problem. If the page is indexed but rarely shown, improving its accessibility to crawlers may not be the most useful next step. Think of the stages as a way to ask better questions, not as a formula that guarantees visibility.
Discovery: how a search engine finds a URL
Search engines can discover pages by following links from pages they already know. A clear site structure helps: a visitor should be able to move from a main navigation page or relevant category page to important content through ordinary links. Internal links also give context. A descriptive link such as “beginner’s guide to keyword research” tells readers more about the destination than “click here.”
An XML sitemap is another way to list URLs you want search engines to consider. It can be especially useful when a site is new or has many pages, but submitting a sitemap does not ensure that every listed page will be crawled or indexed. Keep it focused on pages you intend people to find in search, and update it when those pages change.
Check that important pages are not isolated. If a useful guide exists only at a URL you share directly, adding it to a relevant category page may help both visitors and crawlers reach it.
Crawling and indexing: access is not inclusion
Crawling is the process of requesting a page and examining what it returns. A search engine may have trouble doing that if the server is unreliable, the page requires a login, or its resources are difficult to access. Pages that depend heavily on scripts can also be harder to interpret if essential content is unavailable until those scripts run. Make important text and navigation accessible in the page experience, and test key pages rather than assuming they render as expected.
Indexing is a separate decision: a search engine processes a page and may store information about it for possible use in results. A crawl does not guarantee indexing. Near-duplicate pages, thin pages, or pages that appear to offer little distinct value may be less useful to include. If several URLs show substantially the same content, a consistent preferred URL and appropriate canonical signals can help clarify which version you want represented.
Site controls need careful handling. A robots.txt rule can discourage crawling, while a noindex directive asks search engines not to include a page in results when they can access and read that directive. Blocking a page from crawling may prevent a crawler from seeing its noindex instruction. Use these controls for a specific purpose, and verify their effects before applying them broadly.
Ranking: matching a page to a search
An indexed page is eligible to appear, but its position can vary by query and context. Search engines try to return results that address what a person is looking for. A page explaining a concept, for example, may suit someone seeking a beginner’s definition better than a page focused on buying a service. There is no single ranking position that a page holds for every search.
For a website owner, a sound starting point is to choose a clear purpose for each page. Use a title and headings that accurately describe it, answer the main question early, and add enough detail to help the reader act or learn. Related terms can arise naturally from a thorough explanation; repeating a target phrase does not make a page more useful. Clear layout, working links, and a usable mobile experience also help people engage with the content they find.
Treat links and mentions from other sites as potential paths for discovery and signals of context, not as numbers to manufacture. Focus on creating resources worth referring to rather than pursuing a promised ranking shortcut.
A practical way to check what needs attention
Start with one important page and follow the stages in order. Can someone reach it through your site’s navigation or a related page? Is its URL in your sitemap if it belongs there? Does it load and show its main content without a login? Are any crawl or indexing controls applied intentionally? If multiple URLs serve the same material, is your preferred version clear?
Next, review whether the page answers the search need it targets. Search performance reports and URL inspection tools, when available, can help distinguish an access or indexing issue from a page that is indexed but receives little visibility. Such tools offer clues, not a complete explanation of ranking decisions. Make a focused improvement, then check again over time rather than changing many things at once.
Discovery, indexing, and ranking are related, but each calls for a different response. Keeping useful pages easy to reach, straightforward to interpret, and genuinely helpful to readers gives you a practical foundation for all three.